Multi-Agent Orchestration: Routing and Failure Recovery
Five agents talking to each other destroys context and costs money. Here's the pattern every major vendor converged on: one orchestrator, no loops.
You start with one agent. It works. Then you add more because one agent can't handle customer service + billing + technical support at the same time. Now you have five agents and they're destroying each other.
Agent A sends to Agent B. Agent B doesn't know the context, so it re-asks questions. Agent B sends to Agent C. Agent C thinks it's a new conversation and starts over. Meanwhile Agent D got the same message and is also working on it. Your cost just tripled and your customers are waiting for contradictory responses.
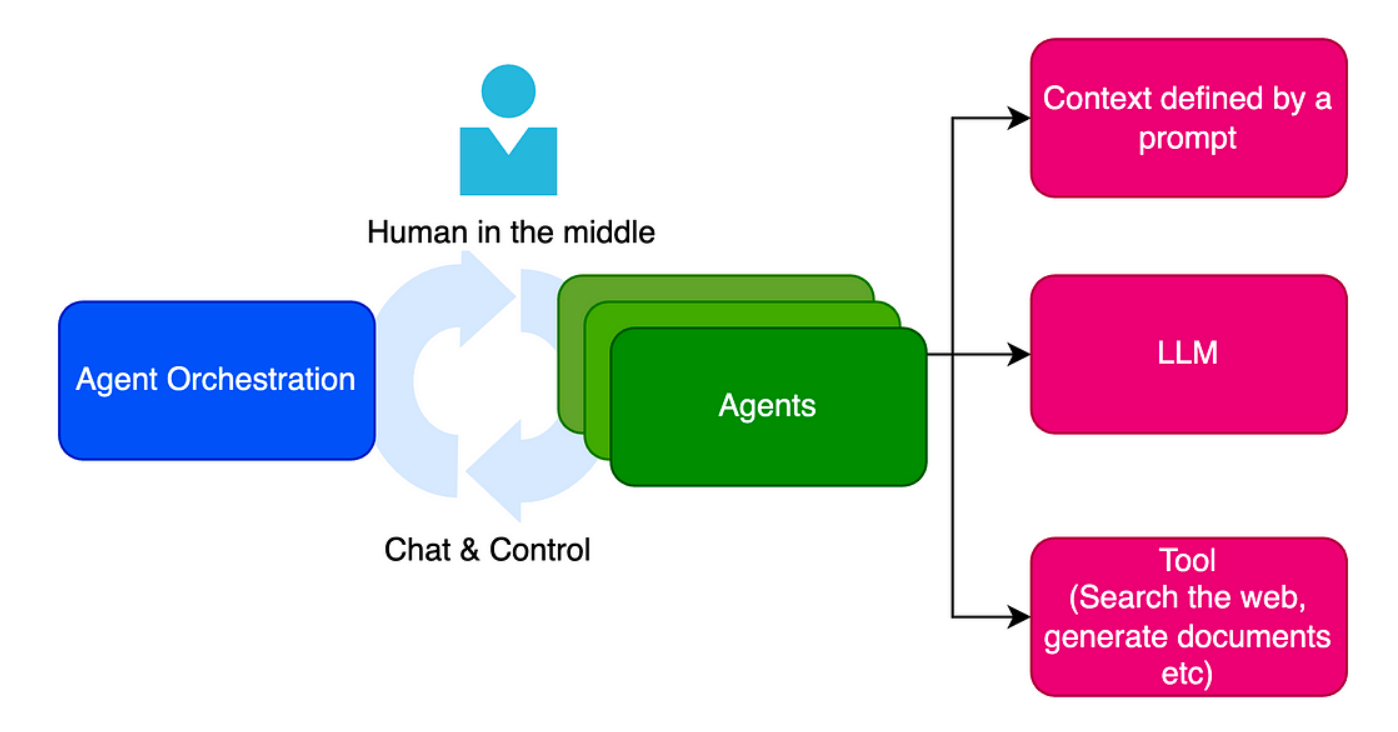 This is what happens when you bolt agents together without an orchestrator. In 2026, the teams that figured this out all converged on the same pattern: one orchestrator owns the conversation, spawns isolated agents for specific tasks, collects their results, and decides what to do next.
No peer-to-peer. No agent-to-agent handoffs. No infinite loops.
This post covers what actually works at scale.
Why Single Agents Don't Scale
A single agent with access to everything sounds good in theory. In practice:
- Context window explosion — Every tool call, every attempted action, every failure eats tokens. A complex task that needs 20 steps burns through context fast.
- Decision fatigue — The agent re-plans constantly. Should I use tool A or B? Should I retry or escalate? With 10 tools available, it thrashes.
- Liability — Everything the agent does is one entity. If it makes a mistake, there's no clear separation of concerns. No audit trail of "who decided what."
- Recovery is hard — When the agent fails partway through, where does it resume? You have to restart the whole thing.
Example of agent thrashing:
User: "I need a refund but also want to keep my subscription"

Agent thinks:
- Should I use get_refund tool?
- But the policy says refunds end subscription
- Should I ask the user to clarify?
- Should I escalate to billing?
- Actually, let me just try both

Result: Makes refund call AND tries to keep subscription
Outcome: Inconsistent state, confused customer, support ticket
With an orchestrator:
1. Orchestrator routes to "refund_agent" because user mentioned refund
2. Refund_agent is narrowly scoped: can only check policies and create refund
3. Refund_agent says "this ends subscription per policy"
4. Orchestrator decides: if customer still wants it, route to "retention_agent"
5. Retention_agent handles upgrade/alternative solutions
6. Clear sequence, clear responsibilities, clear audit trail
The Orchestrator Pattern (What Actually Works)
There's a reason every major vendor converged here. It's the only pattern that scales without chaos.
from typing import List, Dict, Any
from dataclasses import dataclass
from enum import Enum

class AgentType(Enum):
    """Types of agents available."""
    SUPPORT = "support"
    BILLING = "billing"
    TECHNICAL = "technical"
    ESCALATION = "escalation"

@dataclass
class Agent:
    """Agent definition."""
    name: str
    type: AgentType
    system_prompt: str
    tools: List[str]  # Tools this agent can use
    max_steps: int = 5  # Prevent runaway agents

@dataclass
class AgentResult:
    """Result from agent execution."""
    agent_name: str
    success: bool
    output: str
    used_steps: int
    cost: float

class Orchestrator:
    """
    Central orchestrator that owns conversation context.

    Responsibilities:
    - Route messages to appropriate agents
    - Maintain conversation history
    - Collect results and decide next action
    - Handle failures and retries
    - No agent talks to another agent
    """

    def __init__(self):
        self.agents = self._initialize_agents()
        self.conversation_history = []
        self.max_turns = 10
        self.turn_count = 0

    def _initialize_agents(self) -> Dict[str, Agent]:
        """Initialize available agents."""
        return {
            "support": Agent(
                name="support",
                type=AgentType.SUPPORT,
                system_prompt="""You handle customer support queries.
You can only access: get_faq, create_ticket, get_order_status.
Do not make refunds. Do not change subscriptions.
If customer needs those, say so and stop.""",
                tools=["get_faq", "create_ticket", "get_order_status"],
            ),
            "billing": Agent(
                name="billing",
                type=AgentType.BILLING,
                system_prompt="""You handle billing and refunds.
You can only access: process_refund, update_subscription, view_invoice.
Do not handle technical issues or general support.
If customer has those, say so and stop.""",
                tools=["process_refund", "update_subscription", "view_invoice"],
            ),
            "technical": Agent(
                name="technical",
                type=AgentType.TECHNICAL,
                system_prompt="""You handle technical issues.
You can only access: run_diagnostic, restart_service, check_logs.
Do not handle billing or general support.
If customer needs those, say so and stop.""",
                tools=["run_diagnostic", "restart_service", "check_logs"],
            ),
        }

    def process_message(self, user_message: str) -> Dict[str, Any]:
        """
        Process user message through orchestration.

        Steps:
        1. Route to appropriate agent
        2. Agent executes with limited tools
        3. Evaluate result
        4. Decide if done or need another agent
        """
        if self.turn_count >= self.max_turns:
            return {
                "response": "I've tried multiple approaches but can't resolve this. "
                           "Escalating to human support.",
                "status": "escalated",
                "turns_used": self.turn_count,
            }

        self.turn_count += 1

        # Step 1: Route message
        agent_name = self._route_message(user_message)
        agent = self.agents[agent_name]

        # Step 2: Execute agent (isolated, with timeout)
        result = self._execute_agent(agent, user_message)

        # Step 3: Record in history (for transparency)
        self.conversation_history.append({
            "turn": self.turn_count,
            "user_message": user_message,
            "routed_to": agent_name,
            "result": result,
        })

        # Step 4: Decide next action
        if result.success:
            return {
                "response": result.output,
                "status": "resolved",
                "agent_used": agent_name,
                "turns_used": self.turn_count,
            }
        elif self._should_escalate(result):
            return self._escalate_to_human(result)
        else:
            # Try a different agent (only once per message)
            alternative = self._find_alternative_agent(agent_name, user_message)
            if alternative:
                self.conversation_history[-1]["note"] = "First agent failed, trying alternative"
                user_message = f"First agent couldn't help. Original question: {user_message}"
                return self.process_message(user_message)
            else:
                return {
                    "response": "I couldn't resolve this. " + result.output,
                    "status": "failed",
                    "agent_used": agent_name,
                    "turns_used": self.turn_count,
                }

    def _route_message(self, message: str) -> str:
        """
        Route message to appropriate agent.

        Logic:
        1. Look for keywords (refund → billing, error → technical)
        2. If multiple, prioritize by severity
        3. Default to support if unclear
        """
        message_lower = message.lower()

        # Keyword-based routing (simple but effective)
        routing_rules = {
            "billing": ["refund", "payment", "invoice", "charge", "subscription"],
            "technical": ["error", "broken", "crash", "not working", "slow", "timeout"],
            "support": ["question", "how to", "help", "confused"],
        }

        scores = {}
        for agent, keywords in routing_rules.items():
            scores[agent] = sum(1 for kw in keywords if kw in message_lower)

        # Return agent with highest score, or default to support
        best_agent = max(scores, key=scores.get) if max(scores.values()) > 0 else "support"
        return best_agent

    def _execute_agent(self, agent: Agent, message: str, timeout: int = 30) -> AgentResult:
        """
        Execute agent with safety constraints.

        Safety measures:
        - Timeout: agent can't run forever
        - Step limit: agent can't make 100 tool calls
        - Tool scope: agent only has access to assigned tools
        - Isolated context: agent doesn't see other agents' history
        """
        import time
        start_time = time.time()

        try:
            # In production, this would:
            # 1. Call the agent with isolated context
            # 2. Monitor step count
            # 3. Kill if timeout exceeded
            # 4. Return structured result

            # Pseudocode:
            # agent_context = {
            #     "message": message,
            #     "tools": agent.tools,
            #     "history": [h for h in self.conversation_history
            #                 if h["routed_to"] == agent.name]  # Only this agent's history
            # }
            # response = call_llm(agent.system_prompt, message, context=agent_context)
            # steps_used = count_tool_calls(response)

            # For now, return mock result
            elapsed = time.time() - start_time

            return AgentResult(
                agent_name=agent.name,
                success=True,
                output=f"Agent {agent.name} processed: {message[:50]}...",
                used_steps=2,
                cost=0.05,
            )

        except TimeoutError:
            return AgentResult(
                agent_name=agent.name,
                success=False,
                output=f"Agent {agent.name} exceeded timeout",
                used_steps=agent.max_steps,
                cost=0.10,
            )
        except Exception as e:
            return AgentResult(
                agent_name=agent.name,
                success=False,
                output=f"Agent {agent.name} failed: {str(e)}",
                used_steps=0,
                cost=0.0,
            )

    def _should_escalate(self, result: AgentResult) -> bool:
        """Determine if we should escalate to human."""
        # Escalate if:
        # - Agent failed after using max steps
        # - Agent explicitly said "escalate"
        # - Same issue tried twice
        return result.used_steps >= 4 or "escalate" in result.output.lower()

    def _find_alternative_agent(self, current_agent: str, message: str) -> str:
        """Find different agent to try."""
        # Don't retry same agent
        # Don't try more than once per user message
        # Just try support as catch-all
        if current_agent != "support":
            return "support"
        return None

    def _escalate_to_human(self, result: AgentResult) -> Dict[str, Any]:
        """Escalate to human support."""
        return {
            "response": "I need to escalate this to our support team. "
                       f"They'll contact you shortly. (Agent: {result.agent_name})",
            "status": "escalated",
            "reason": result.output,
        }
Routing Strategies
Simple keyword matching works for 80% of cases. But get routing wrong and you waste time.
class Router:
    """
    Different routing strategies for different scenarios.
    """

    @staticmethod
    def keyword_routing(message: str, rules: Dict[str, List[str]]) -> str:
        """
        Keyword-based routing (simple, fast).

        Pros: No AI calls, instant, predictable
        Cons: Misses nuance, needs manual rules
        """
        scores = {}
        for agent, keywords in rules.items():
            scores[agent] = sum(1 for kw in keywords if kw in message.lower())
        return max(scores, key=scores.get) or "default"

    @staticmethod
    def intent_routing(message: str, classifier) -> str:
        """
        ML-based intent classification (better accuracy).

        Steps:
        1. Classify message intent (refund, bug report, question)
        2. Map intent to agent
        3. Return agent name

        Pros: Handles paraphrasing, more accurate
        Cons: ~100ms latency, costs money
        """
        intent = classifier.predict(message)
        intent_to_agent = {
            "refund": "billing",
            "bug": "technical",
            "question": "support",
        }
        return intent_to_agent.get(intent, "support")

    @staticmethod
    def hybrid_routing(message: str, keywords: Dict, classifier, threshold: float = 0.5) -> str:
        """
        Hybrid: fast path + fallback to classifier.

        Logic:
        1. Try keyword routing first (0ms)
        2. If no clear match (score < threshold), use classifier
        3. Return confident routing

        Pros: Fast for common cases, accurate for edge cases
        Cons: Complexity, two paths to maintain
        """
        keyword_agent = Router.keyword_routing(message, keywords)
        keyword_score = Router._score_keyword_match(message, keywords[keyword_agent])

        if keyword_score >= threshold:
            return keyword_agent  # Fast path
        else:
            return Router.intent_routing(message, classifier)  # Accurate path

    @staticmethod
    def _score_keyword_match(message: str, keywords: List[str]) -> float:
        """Score how well keywords match (0-1)."""
        matches = sum(1 for kw in keywords if kw in message.lower())
        return matches / len(keywords) if keywords else 0
Handoff Without Infinite Loops
This is where most teams fail. They create Agent A → Agent B → Agent C → Agent A infinite loop.
from dataclasses import dataclass
from typing import Optional, Set

@dataclass
class HandoffState:
    """Track handoffs to prevent loops."""
    current_agent: str
    previous_agents: Set[str]  # Agents already tried
    handoff_count: int = 0
    max_handoffs: int = 2  # Never handoff more than twice
    root_message: str = None  # Original user message (immutable)

class SafeHandoff:
    """
    Orchestrate handoffs safely.

    Rules:
    1. Never handoff to agent that already handled this message
    2. Never more than N handoffs
    3. Always send full context, not partial
    4. Record handoff reason for debugging
    """

    @staticmethod
    def can_handoff_to(
        target_agent: str,
        state: HandoffState,
    ) -> bool:
        """Check if handoff is safe."""
        # Prevent revisiting same agent
        if target_agent in state.previous_agents:
            return False

        # Prevent excessive handoffs
        if state.handoff_count >= state.max_handoffs:
            return False

        return True

    @staticmethod
    def execute_handoff(
        from_agent: str,
        to_agent: str,
        message: str,
        state: HandoffState,
        reason: str = "",
    ) -> HandoffState:
        """
        Execute handoff with full context.

        What NOT to do:
        - Pass partial context ("just the error message")
        - Lose information in translation
        - Have agent re-ask questions

        What to do:
        - Pass full conversation history
        - Provide explicit reason for handoff
        - Include what from_agent already tried
        """

        # Update state
        new_state = HandoffState(
            current_agent=to_agent,
            previous_agents=state.previous_agents | {from_agent},
            handoff_count=state.handoff_count + 1,
            root_message=state.root_message or message,
        )

        # Build handoff context
        handoff_context = {
            "original_message": new_state.root_message,
            "handoff_reason": reason,
            "previous_agent": from_agent,
            "agents_already_tried": new_state.previous_agents,
            "current_message": message,
        }

        # Pass to next agent with FULL context
        # agent_prompt = f"""
        # {to_agent_system_prompt}
        #
        # HANDOFF CONTEXT:
        # Original request: {handoff_context['original_message']}
        # Reason for handoff: {handoff_context['handoff_reason']}
        # Already tried: {', '.join(handoff_context['agents_already_tried'])}
        #
        # Current message: {handoff_context['current_message']}
        # """

        return new_state

    @staticmethod
    def is_loop_detected(state: HandoffState) -> bool:
        """Detect if we're in a handoff loop."""
        # Simple detection: if any agent appears twice, it's a loop
        if len(state.previous_agents) > len(set(state.previous_agents)):
            return True

        # Or if we've hit max handoffs
        if state.handoff_count >= state.max_handoffs:
            return True

        return False
Failure Recovery
Failures happen. What matters is recovering without repeating yourself.
from enum import Enum
from typing import Callable

class RecoveryStrategy(Enum):
    """How to recover from agent failure."""
    RETRY = "retry"  # Try same agent again
    ALTERNATE = "alternate"  # Try different agent
    ESCALATE = "escalate"  # Send to human
    DECOMPOSE = "decompose"  # Break into smaller tasks

class FailureRecovery:
    """
    Handle agent failures gracefully.

    Recovery decision tree:
    1. Is it a transient error (timeout, rate limit)? → RETRY
    2. Is it a routing mistake? → ALTERNATE
    3. Is it beyond agent capability? → ESCALATE
    4. Is it complex/multi-step? → DECOMPOSE
    """

    @staticmethod
    def recover(
        agent_name: str,
        error: Exception,
        attempt_count: int,
        state: HandoffState,
    ) -> tuple[RecoveryStrategy, Optional[str]]:
        """
        Decide recovery strategy.

        Returns: (strategy, target_agent or reason)
        """

        error_type = type(error).__name__
        error_msg = str(error).lower()

        # Transient errors: retry (but not forever)
        if error_type in ["TimeoutError", "ConnectionError"]:
            if attempt_count < 2:
                return RecoveryStrategy.RETRY, None
            else:
                return RecoveryStrategy.ESCALATE, "Agent timed out multiple times"

        # Rate limits: retry with backoff
        if "rate" in error_msg or "429" in error_msg:
            if attempt_count < 1:
                return RecoveryStrategy.RETRY, None
            else:
                return RecoveryStrategy.ESCALATE, "Rate limited"

        # Permission/capability errors: try alternate agent
        if "permission" in error_msg or "not authorized" in error_msg:
            return RecoveryStrategy.ALTERNATE, None

        # Complex tasks: decompose
        if "too complex" in error_msg or len(state.previous_agents) > 1:
            return RecoveryStrategy.DECOMPOSE, None

        # Default: escalate
        return RecoveryStrategy.ESCALATE, str(error)

    @staticmethod
    def execute_recovery(
        strategy: RecoveryStrategy,
        agent_name: str,
        message: str,
        state: HandoffState,
        orchestrator,
    ) -> Dict[str, Any]:
        """Execute recovery action."""

        if strategy == RecoveryStrategy.RETRY:
            # Wait a bit, then retry
            import time
            time.sleep(1)
            return orchestrator._execute_agent(
                orchestrator.agents[agent_name],
                message,
            )

        elif strategy == RecoveryStrategy.ALTERNATE:
            # Try different agent
            alternative = orchestrator._find_alternative_agent(agent_name, message)
            if alternative:
                return SafeHandoff.execute_handoff(
                    agent_name, alternative, message, state,
                    reason="First agent failed with permission error"
                )

        elif strategy == RecoveryStrategy.ESCALATE:
            # Send to human
            return orchestrator._escalate_to_human(
                AgentResult(agent_name, False, strategy.value, 0, 0)
            )

        elif strategy == RecoveryStrategy.DECOMPOSE:
            # Break into subtasks
            subtasks = orchestrator._decompose_task(message)
            results = []
            for subtask in subtasks:
                result = orchestrator.process_message(subtask)
                results.append(result)
            return {"response": " ".join(r["response"] for r in results), "status": "resolved"}
Production Checklist
Before you ship multi-agent orchestration:
- No peer-to-peer — Agents only talk to orchestrator
- Isolated context — Agent doesn't see other agents' work
- Loop detection — Can't handoff to same agent twice
- Timeout protection — Agent can't run forever
- Tool scoping — Agent only has access to relevant tools
- Failure recovery — Can distinguish transient vs permanent failures
- Audit trail — Every routing/handoff decision is logged
- Escalation path — Clear handoff to human when needed
- Cost tracking — Know which agent is expensive
- Testing — Tested with "malicious" inputs that try to break routing
Common Failure Modes (And How to Prevent Them)
Problem 1: Infinite Handoff Loop
Agent A says "this is a refund question" → routes to Agent B Agent B says "this is a technical issue" → routes to Agent C
Agent C says "this is a support question" → routes to Agent A
Result: Loop forever, user confused, cost skyrockets.
Prevention:
# Keep track of agents already tried
# Never handoff to an agent that already handled this message
if target_agent in state.previous_agents:
    escalate_to_human()  # Not loop back
Problem 2: Context Loss on Handoff
Agent A does 5 steps, then hands off to Agent B with just "Please help with this" Agent B doesn't know what A tried, asks same questions, wastes effort.
Prevention:
# Always pass FULL context on handoff
handoff_context = {
    "original_message": user_message,
    "what_agent_a_tried": [step1, step2, ...],
    "why_handoff": reason,
    "current_state": full_history,
}
# Agent B gets complete picture
Problem 3: Agent Explosion (Too Many Agents)
You have 20 agents because someone said "modular". Now routing is broken because every message matches multiple agents. Maintenance is nightmare.
Prevention:
# Start with 3-5 agents max
# Each agent has ONE clear responsibility
# Add agents only when you have concrete evidence of need
# (e.g., "these 3 queries always fail with agent X")
Problem 4: Trusting Agent Self-Assessment
Agent decides "I handled this" when it clearly didn't.
Prevention:
# Don't ask agent if it succeeded
# Look at actual outcomes:
# - Did we call the right tool?
# - Did the tool return success?
# - Did the user get what they asked for?
Real Example: E-Commerce Support
# User: "I got charged twice but also don't want to cancel"

# Step 1: Orchestrator routes to "billing"
# Step 2: Billing agent checks charges, finds duplicate
# Step 3: Billing agent tries to process refund
# Step 4: Billing agent sees policy: "refund cancels subscription"
# Step 5: Billing agent says "I can refund but it ends subscription"
# Step 6: Orchestrator sees agent can't proceed
# Step 7: Orchestrator decides: should we retry? escalate?
# Step 8: Orchestrator routes to "retention"
# Step 9: Retention agent offers alternatives
# Step 10: Done (clear audit trail, no loops, user helped)
vs
# Without orchestration:
# User: "I got charged twice but also don't want to cancel"

# Step 1: Single agent sees refund + subscription
# Step 2: Agent uncertain: "should I do refund? Or keep subscription?"
# Step 3: Agent tries both (contradiction)
# Step 4: Tries to fix mistakes by calling tools again
# Step 5: Tools call each other, mess things up
# Step 6: Agent burned through context
# Step 7: Fails
# Step 8: User has to start over

# Result: Wasted tokens, confused system, bad customer experience
The Real Talk
Multi-agent systems look chaotic because they ARE chaotic without structure. The teams that ship working multi-agent systems aren't using fancy frameworks or complex algorithms. They're using boring structure:
- One orchestrator that owns context
- Agents with narrow, explicit scope
- Simple routing rules (keywords work)
- Hard limits on handoffs (max 2)
- Automatic escalation when confused
- Logged everything
You don't need agents talking to each other. You need agents talking to an orchestrator that knows what's going on. That's it.